Using news-watch, a scraper I maintain, I collected and cleaned 59,197 article records from 53 Indonesian news sources whose headlines name Prabowo Subianto. The collection runs from his inauguration on 20 October 2024 to 14 August 2026, which gives 23 calendar-month buckets, although the first and last are partial.
This is not a census of everything those portals published, nor is it all
coverage of the administration. It is a deliberately narrower object: retrieved
articles that put prabowo in the headline.
Four things stand out. Within the 43,500 records assigned to a model-generated topic, foreign relations and state visits is the largest theme at 19.0%. Across the full corpus the sentiment model labels 50.6% of records neutral. Law enforcement, corruption and the judiciary is the only theme with a negative plurality. And a person co-mention network shows stronger normalized overlap among a selected group of business figures than among selected senior politicians.
Those findings come with limits. The topic model left 15,697 records unassigned, search access varied sharply between portals, and the sentiment classifier was not trained on news. The numbers describe this retrieved corpus, not public opinion, policy performance, or the full Indonesian news ecosystem.
It is adapted from the full method writeup in the news-watch documentation, which carries the collection commands, the validation gates, the model revisions and the retrieval audits. Read that one to reproduce the corpus. Read this one for what the corpus shows. It is also the companion to the MBG study, which narrows to one programme where this takes a whole presidency.
Published on Indonesia’s 81st Independence Day. Selamat Hari Kemerdekaan.
What the corpus measures
Prabowo was inaugurated on 20 October 2024 and announced the Kabinet Merah Putih that evening. Starting on inauguration day keeps campaign and transition coverage outside the window. It also explains why cabinet coverage is unusually high in the first, partial month.
A record enters the corpus only when its title contains a standalone mention of
prabowo, matched without regard to case. The search ran against 74 stable
registry entries that supported keyword search, and 53 sources contributed
records that survived cleaning.
The title rule gives the study a clear boundary, but it has a substantial cost. Of 90,515 records that fell inside the date window and had unique links, 29,561 were excluded because they mentioned Prabowo only in the body. Another 2,308 of those excluded records named a flagship programme such as Sekolah Rakyat or MBG in the title without naming him there.
I read an exploratory sample of 40 title-excluded records at seed 42. Ten were genuine coverage of Prabowo or his programmes, four were arguable, and 26 used his name mainly as context for the current administration. The sample is too small to estimate the whole excluded pool precisely. It does show why a simple word rule could not separate central coverage from era context reliably.
After cleaning, 43,500 records received one of 111 topics. The remaining 15,697, or 26.5%, fell into the model’s outlier category. Every theme percentage below therefore uses the assigned set as its denominator.
Foreign relations is the largest sustained theme
The 111 model-generated topics were grouped into 17 readable themes. Foreign relations and state visits is the largest, with 8,273 records or 19.0% of the assigned set. Cabinet, appointments and protocol follows at 11.8%. No other theme reaches 12%.
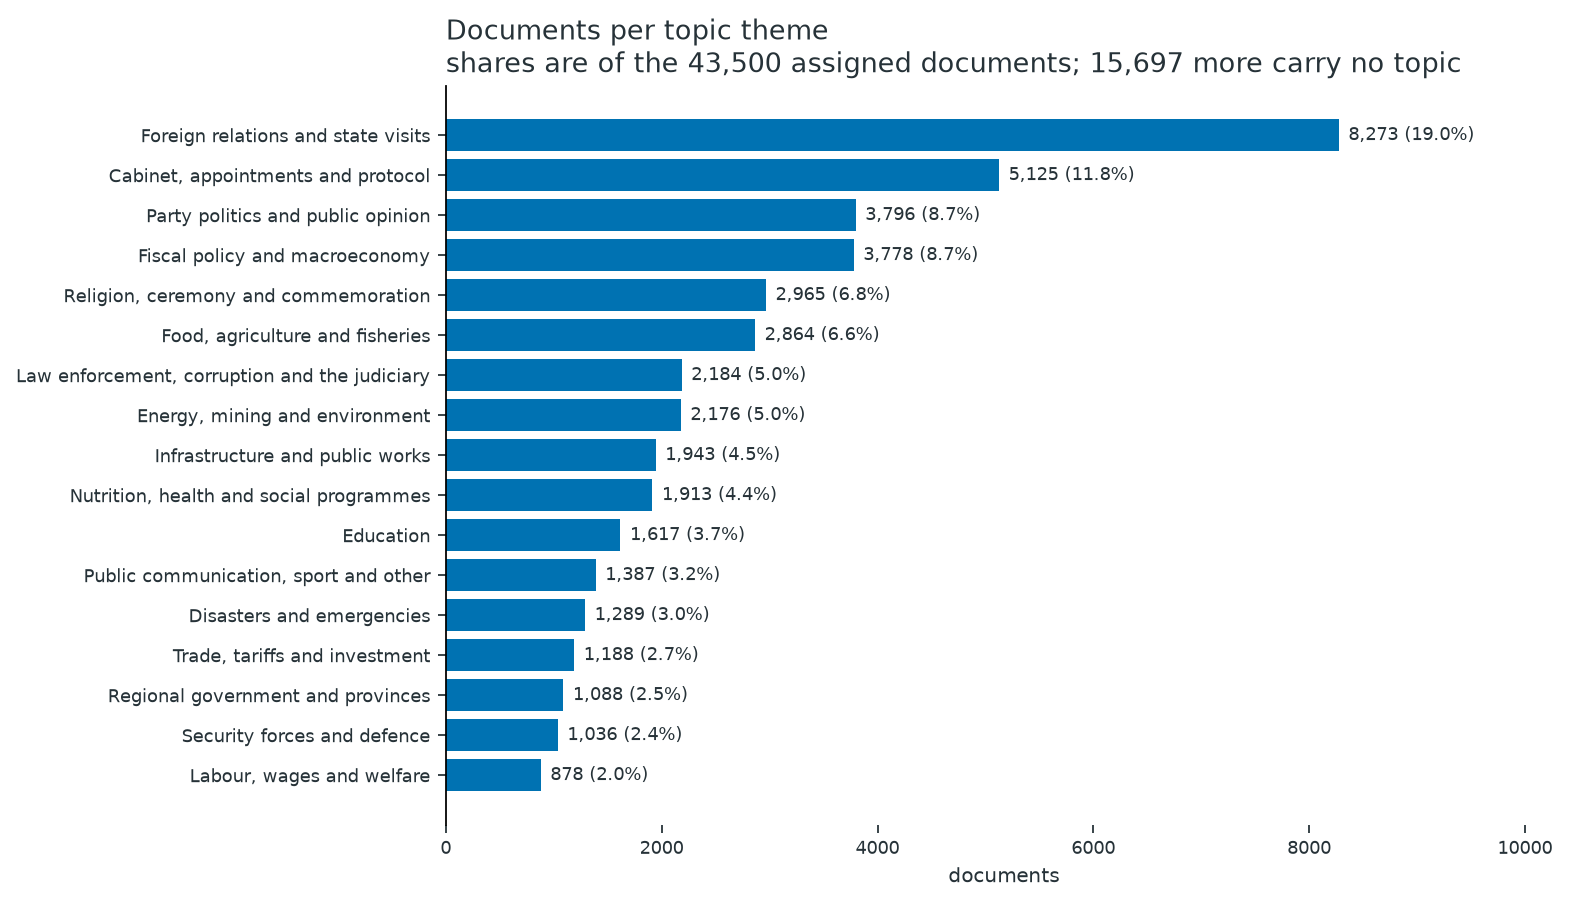
The result is broad rather than tied to one diplomatic counterpart. The underlying topics include Palestine, Russia, China, France, India, Japan, Korea, the Gulf states, ASEAN, the European Union, Brazil and Turkiye. Bilateral meetings are the most regularly reported thing a president does, and the corpus reflects that before it reflects anything else.
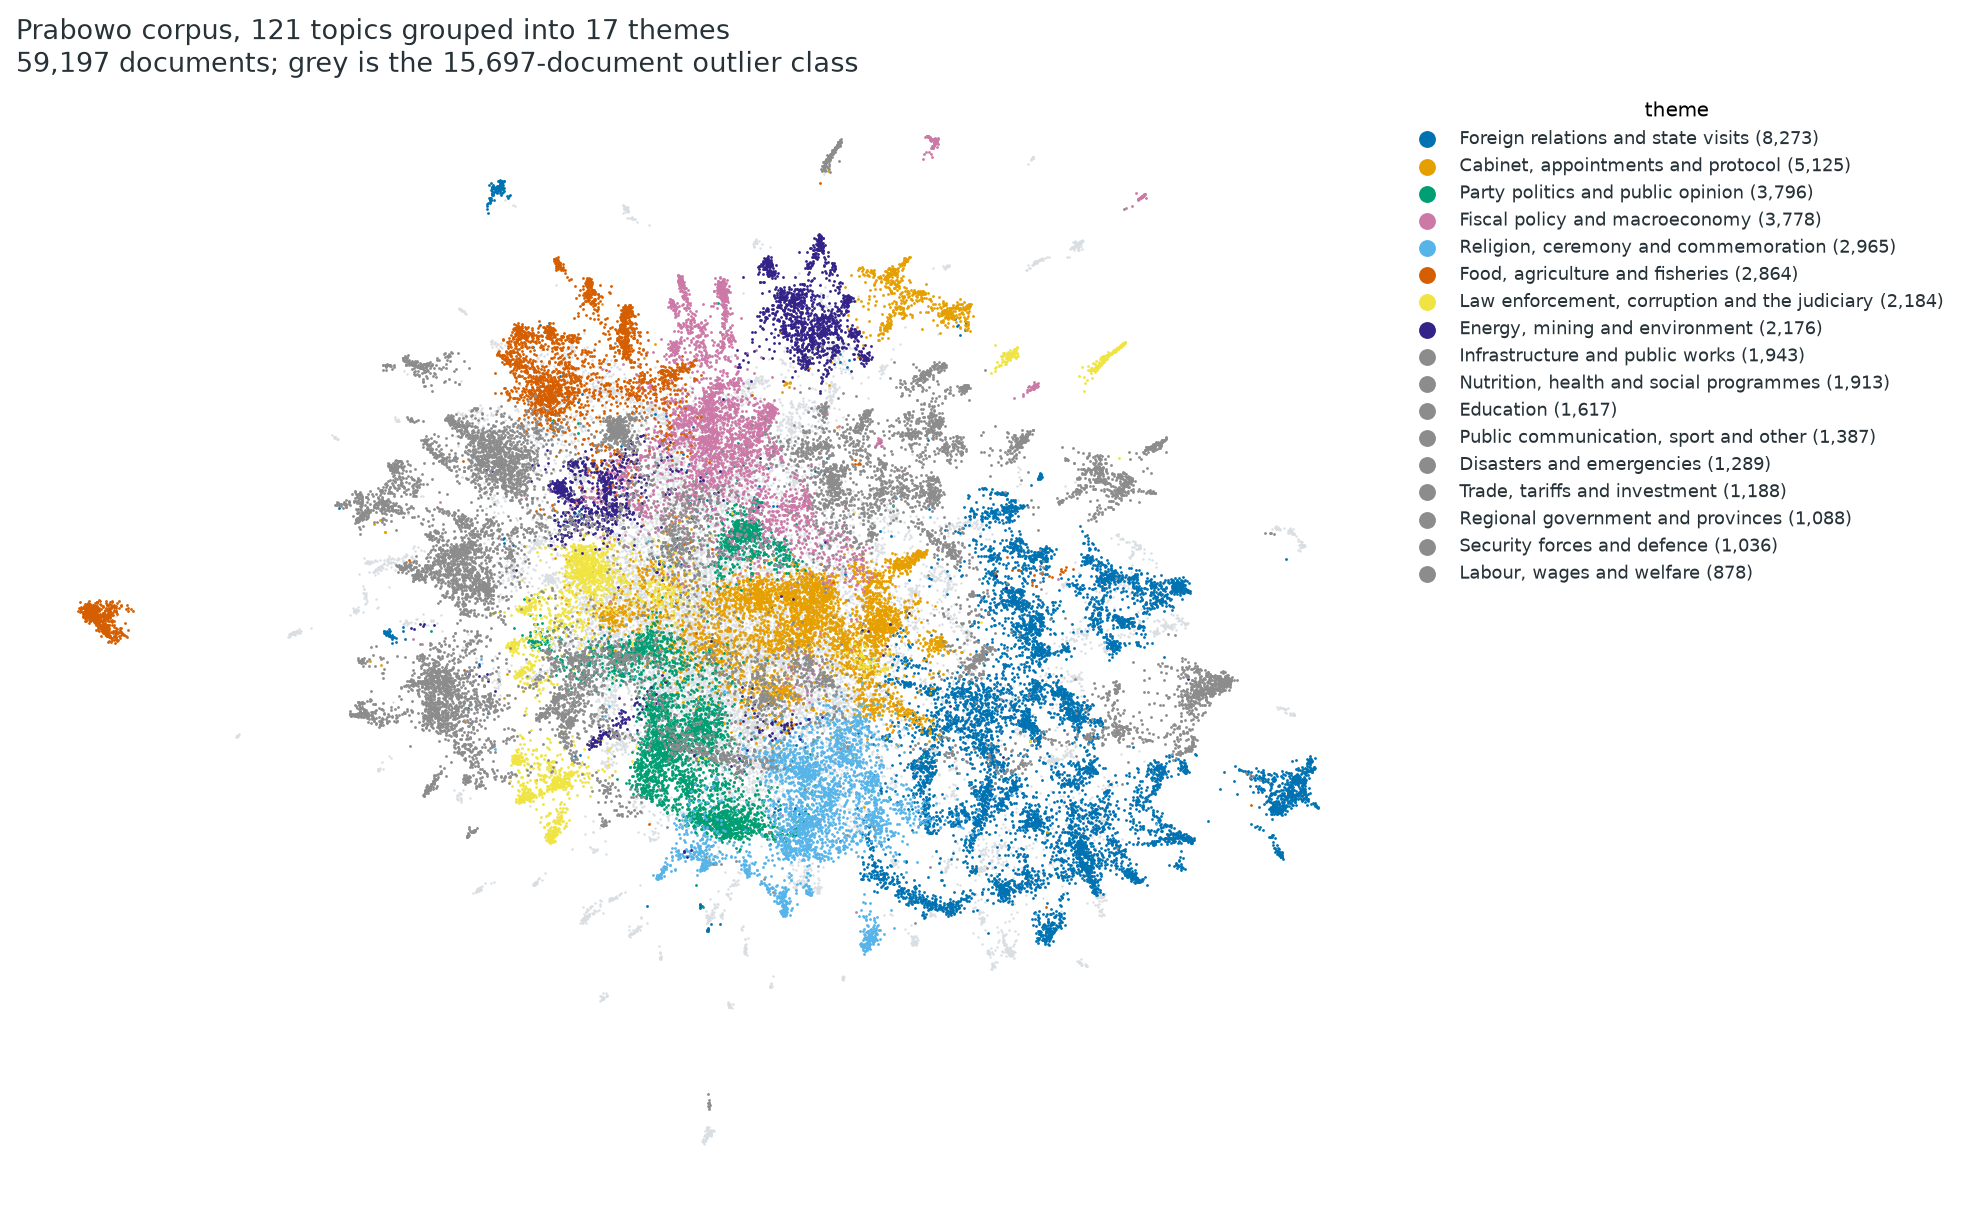
A note on the figure above, because it is easy to misread. It comes from an earlier 121-topic projection of the same 59,197 records. The published analysis later consolidated that fit to the 111 reported topics, so the scatter is retained as a visual diagnostic rather than as a count of the final topic inventory. Each point is a record, and grey points are the 15,697-record outlier class. Distance in a two-dimensional projection is suggestive, not proof that two themes are distinct.
Foreign-relations coverage is also spread more evenly through the window than cabinet coverage. Its busiest month contains 733 assigned records, 1.94 times its median month. Cabinet coverage reaches 1,050 records in October 2024, 6.91 times its median, because the inauguration and the cabinet announcement both fell in that partial month.
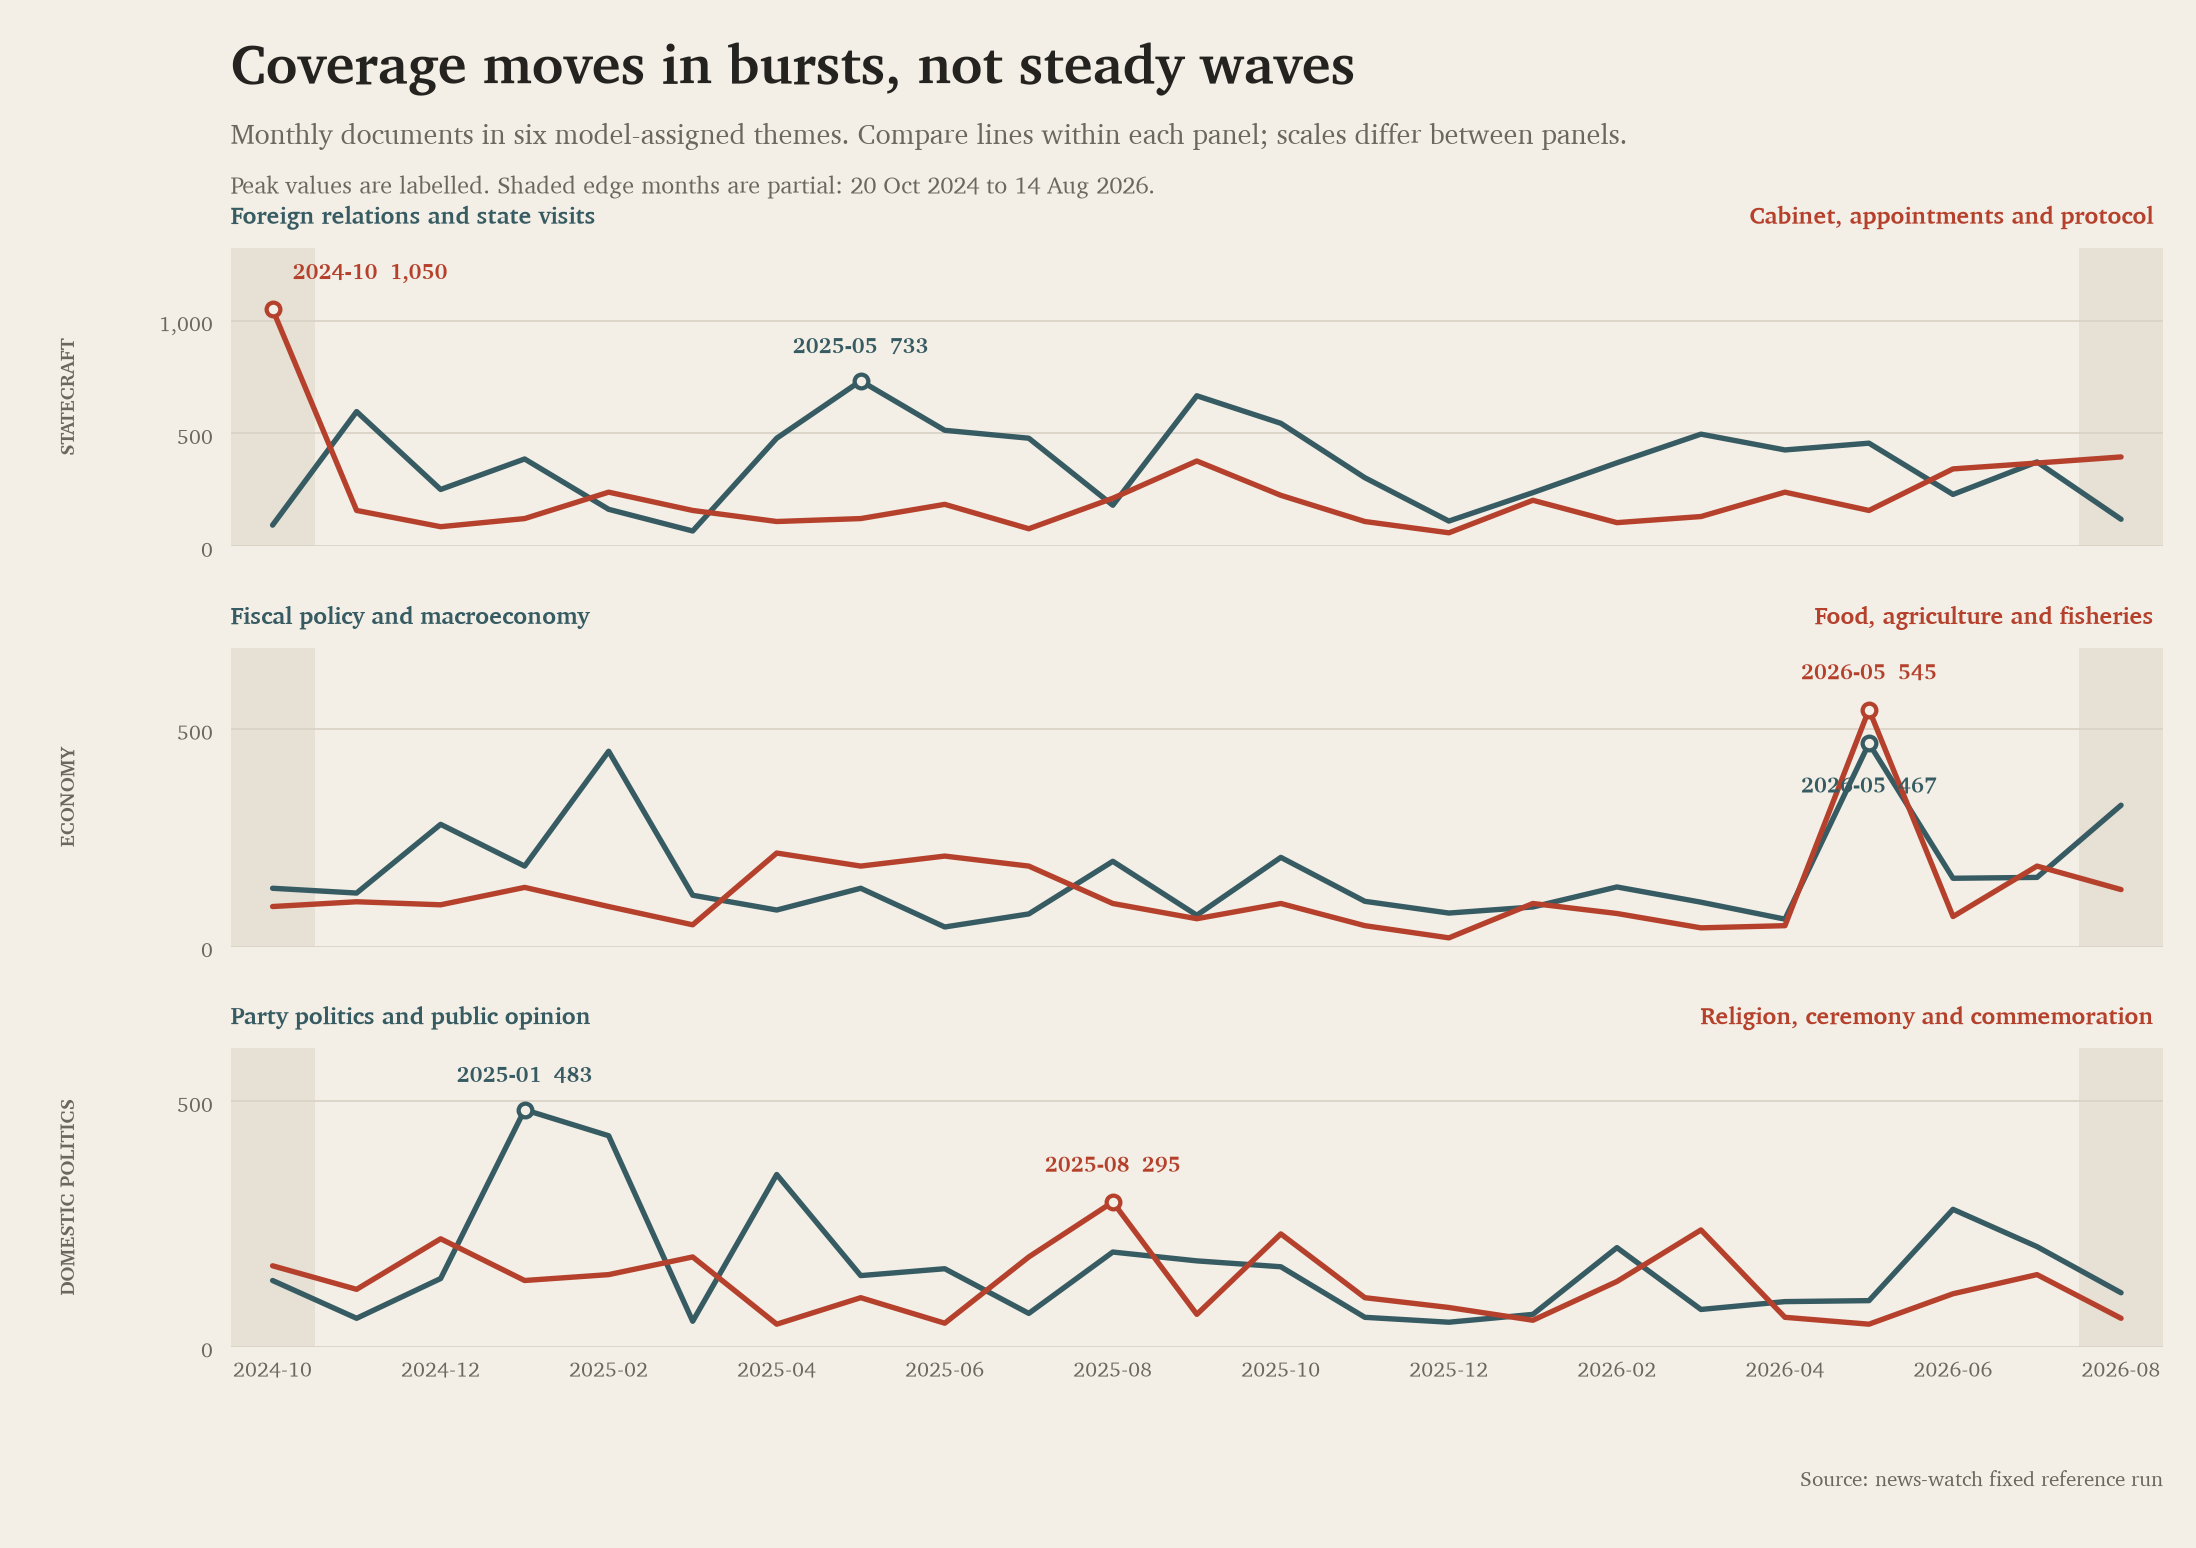
For the six themes in the chart, observed lag-one autocorrelation ranges from -0.13 to +0.05. That provides little evidence of month-to-month persistence in this window. It does not prove that one month contains no information about the next. The chart uses monthly buckets because coarser quarters would conceal the short cabinet and food-policy peaks.
Two sources arrive in bursts rather than across the full period. Wartaekonomi contributes 1,761 records on 96 distinct days, and Jawapos contributes 706 across 170 days. Their absence in other months is a retrieval pattern, not evidence that news volume disappeared. Any time-series use of this corpus should exclude such intermittent sources or account for them explicitly.
The topic partition deserves similar restraint. It is one plausible grouping of a broad corpus, not a definitive taxonomy of the presidency. The fit has no measured cross-seed stability, and a small change to the records could move topic boundaries. That uncertainty is why the analysis keeps 111 topics instead of compressing them into a deceptively tidy dozen.
Most records receive a neutral label
Across all 59,197 records the sentiment model assigns 29,963 neutral labels (50.6%), 17,759 positive (30.0%) and 11,475 negative (19.4%). Meeting readouts, appointments and protocol stories make up much of the collection, so a large neutral share is unsurprising.
Law enforcement, corruption and the judiciary stands apart. It is the only theme where negative is the plurality label, at 44.9%, and it has the lowest mean score at -0.30. The next-lowest displayed mean is -0.08, for labour, wages and welfare. That makes law enforcement the strongest negative outlier. It does not mean the theme contains most of the corpus’s negative records.
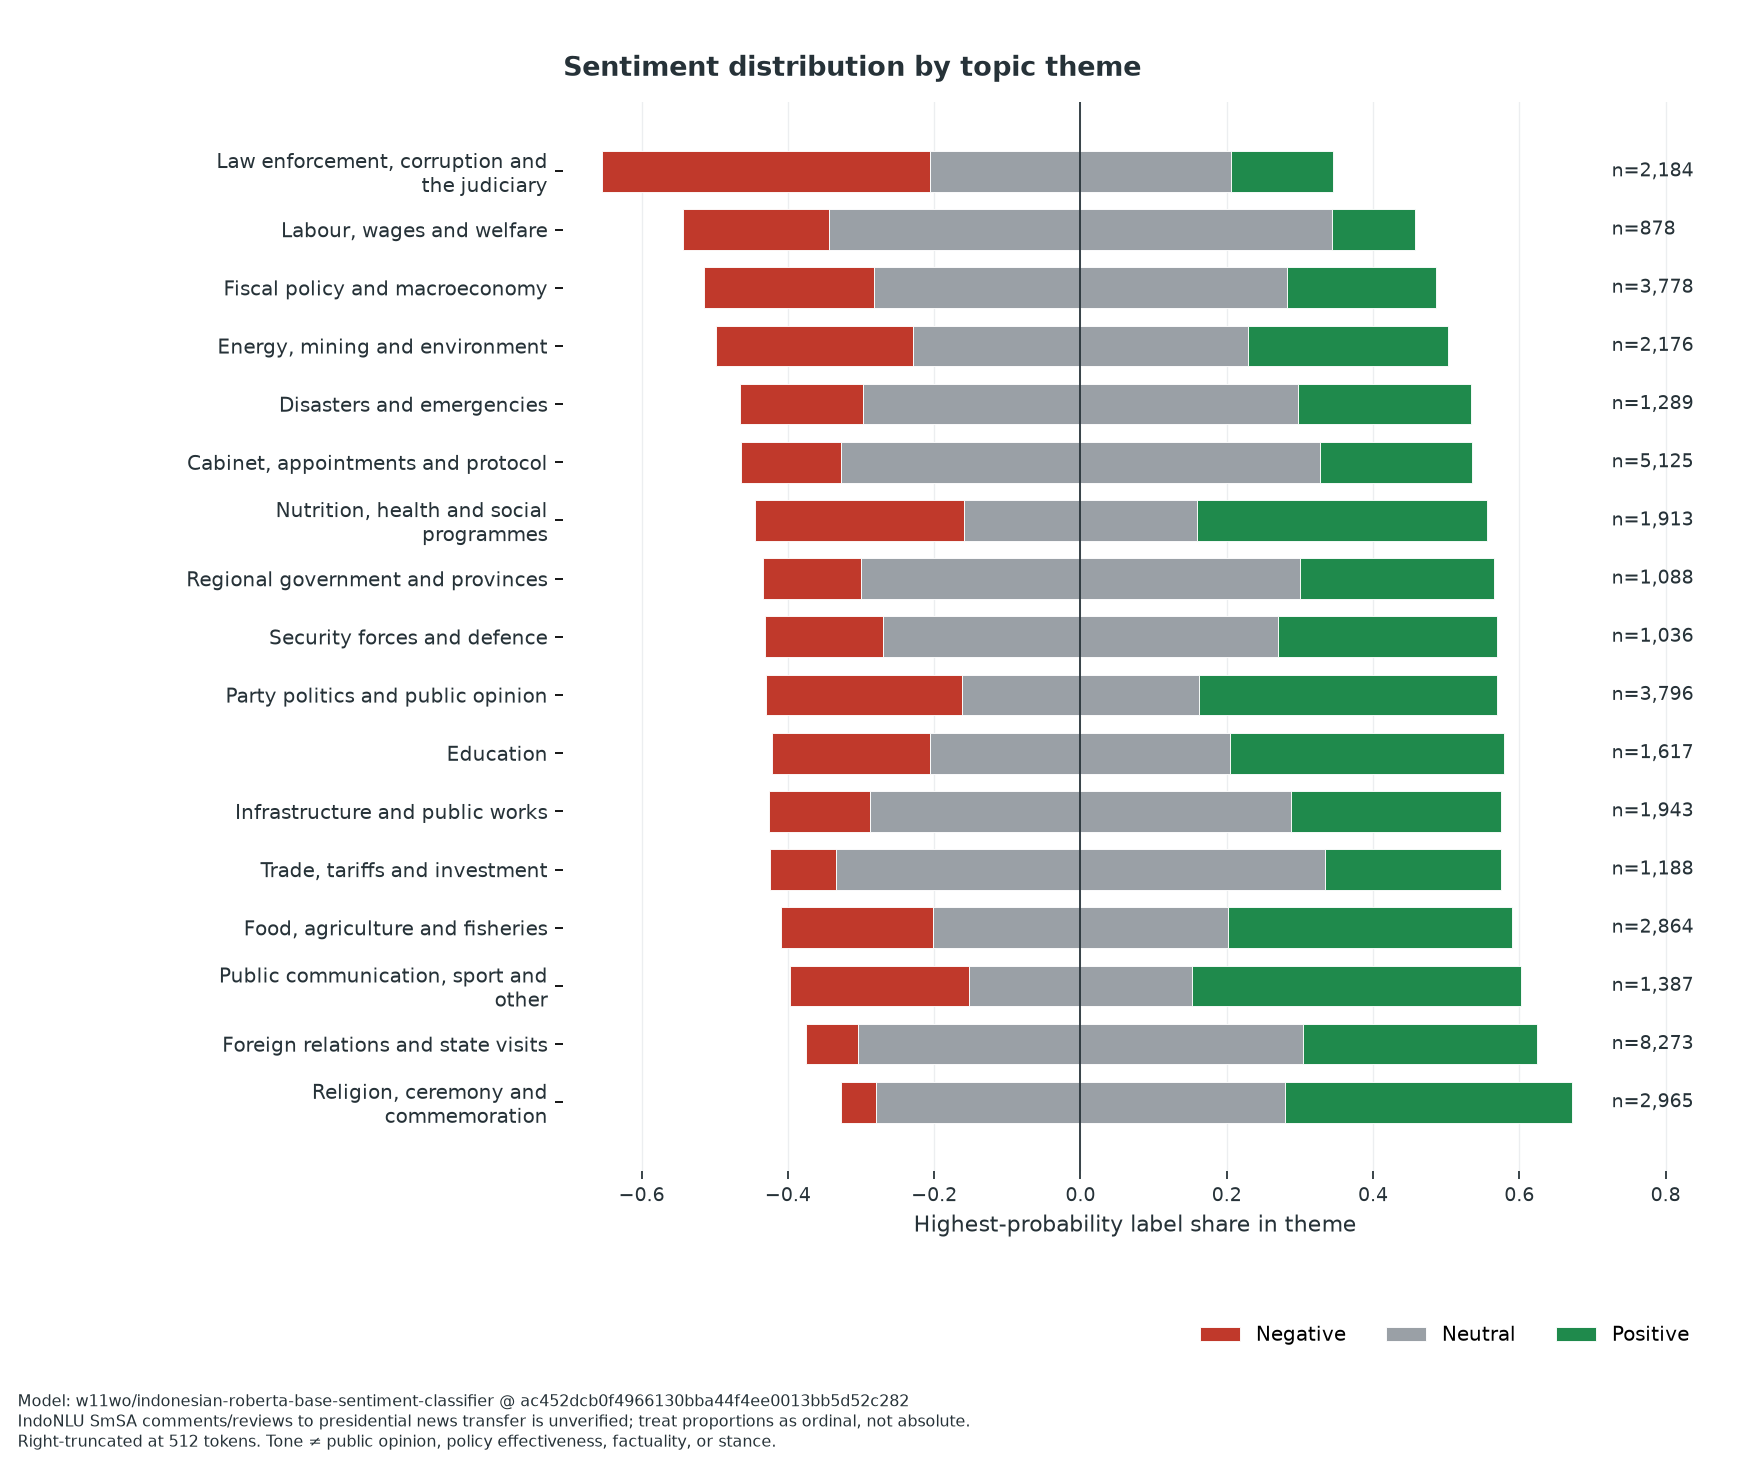
The positive end needs more caution than the negative one. Religion, ceremony and commemoration has the highest mean at +0.33, followed by foreign relations at +0.25. Both contain a great deal of polite protocol language: greetings, congratulations, arrivals and departures. A classifier trained on Indonesian comments and reviews can read that register as positive even when a news report is simply formal.
For that reason, sentiment here means model-assigned language tone in the title and retained article text. It does not measure approval, stance, truth, factuality or policy effectiveness. Long records were truncated from the right at 512 model tokens, which gives the title and opening paragraphs more weight.
In the selected groups, business names overlap more strongly
The person co-mention network asks which names occur in the same retrieved records. It does not infer personal relationships. This is an exploratory, descriptive comparison between two selected groups, not a representative sample of business figures or politicians.
Eight business figures have a mean Jaccard overlap of 0.389 across 28 retained edges. Seven senior politicians have a mean of 0.089 across eight retained edges.
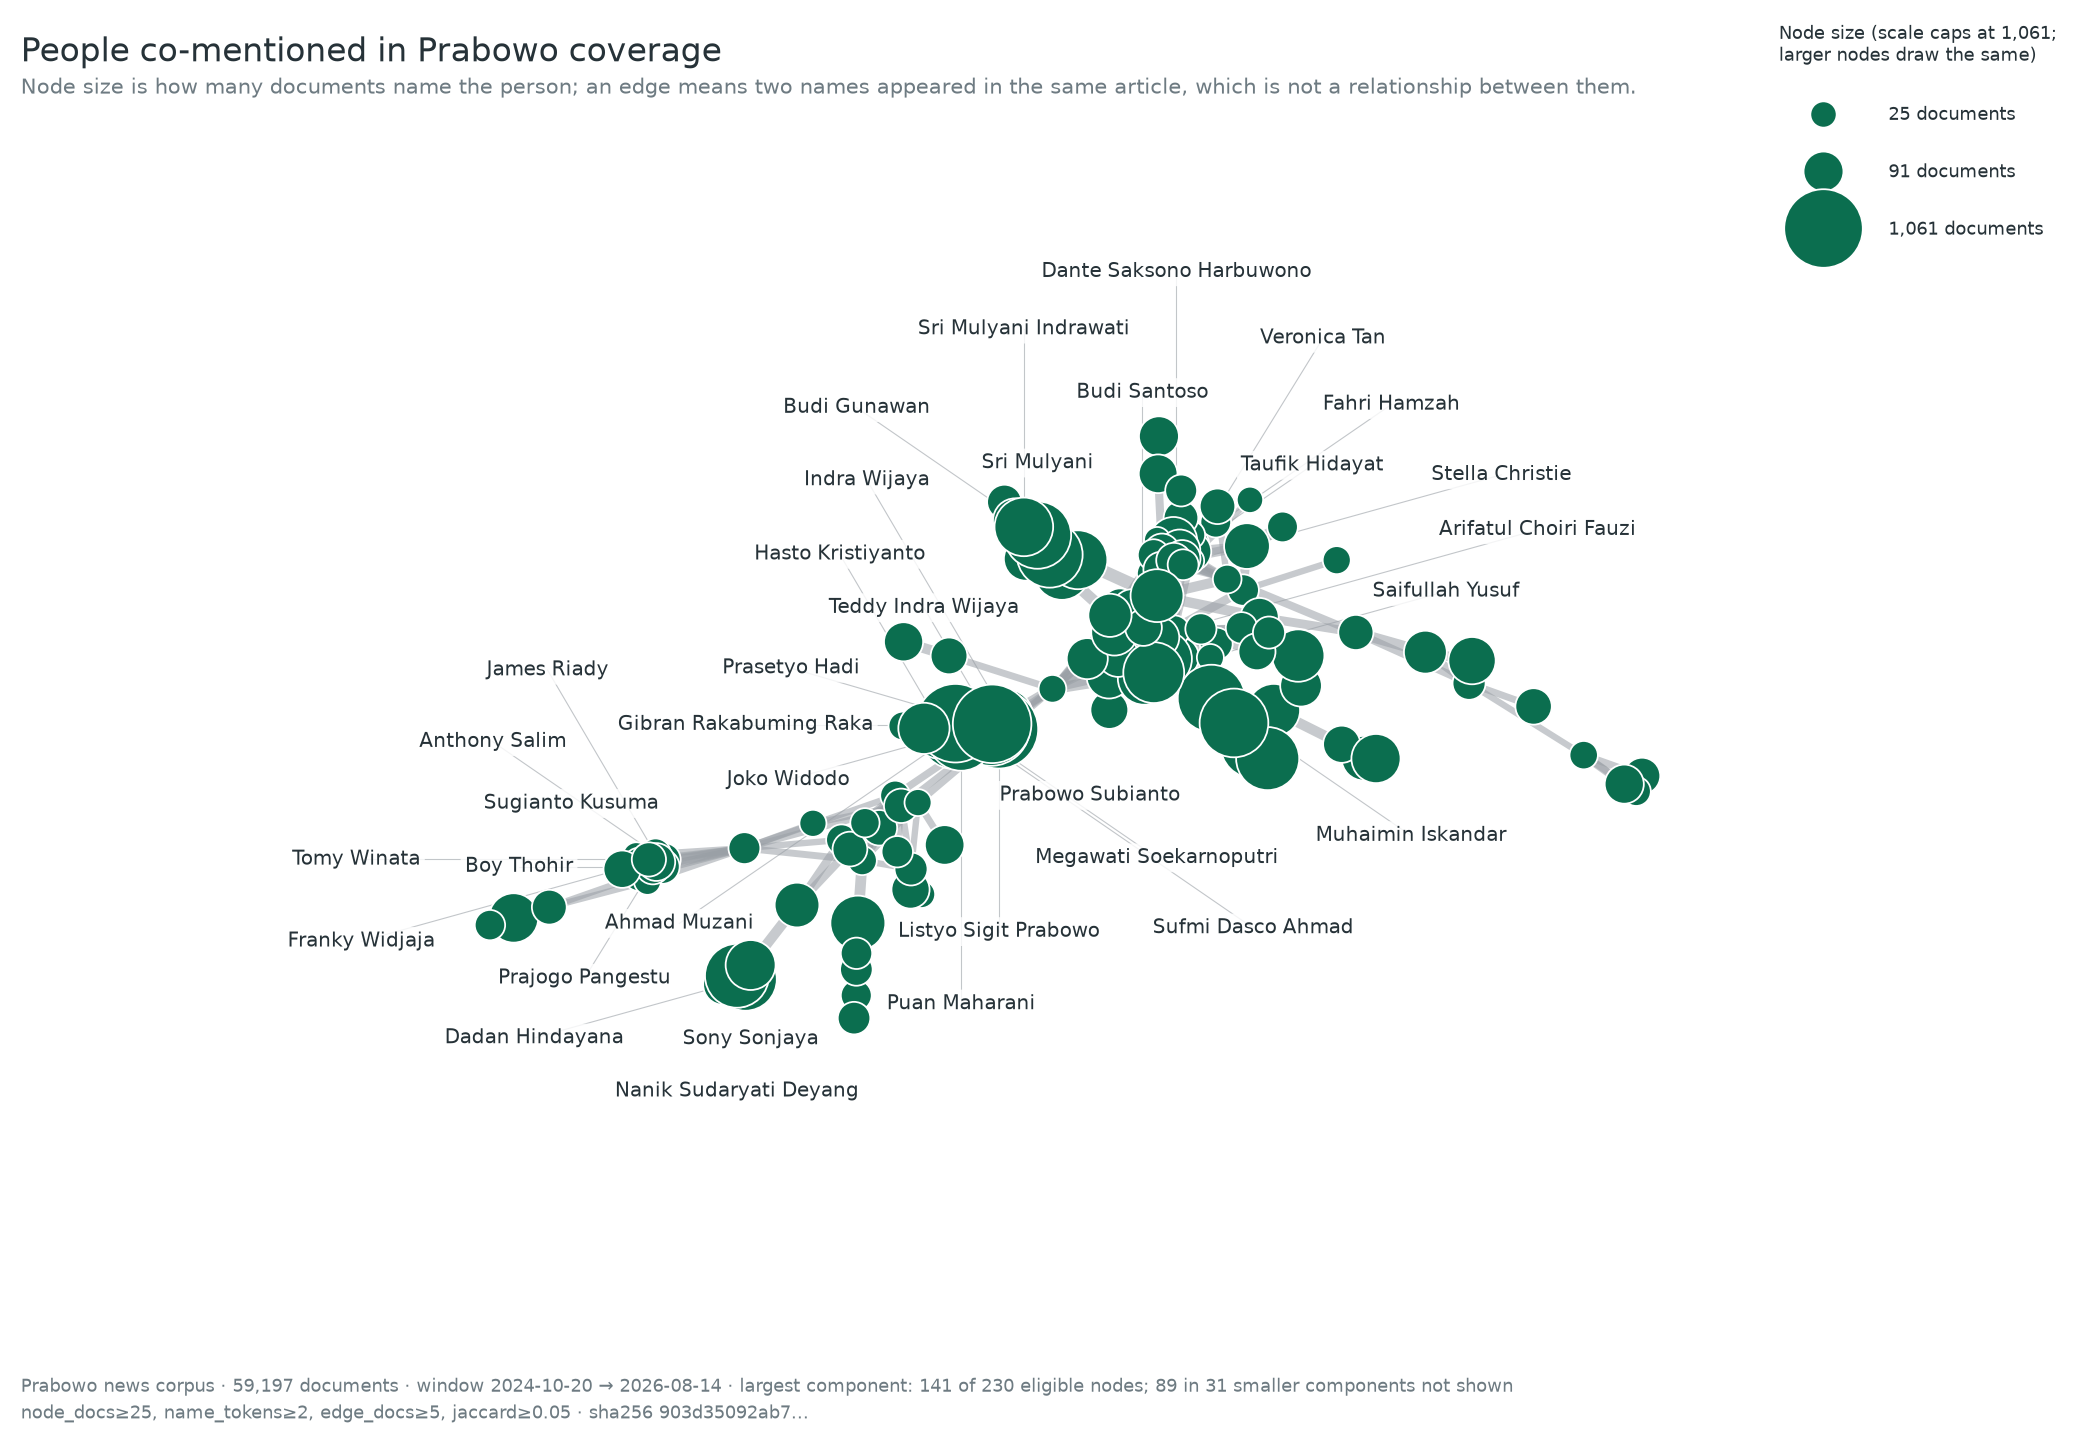
Jaccard measures how strongly two names’ sets of records overlap after accounting for how often each name appears, so the roughly fourfold difference is a difference in normalized co-coverage rather than in raw mention frequency.
The business group consists of Anthony Salim, Boy Thohir, Prajogo Pangestu, Sugianto Kusuma, Franky Widjaja, James Riady, Dato Sri Tahir and Tomy Winata. The political group contains Prabowo, Joko Widodo, Gibran Rakabuming Raka, Megawati Soekarnoputri, Muhaimin Iskandar, Puan Maharani and Ahmad Muzani. The strongest political edge, Gibran with Joko Widodo at 0.160, remains below the weakest business edge in this comparison.
The most plausible reading concerns the shape of coverage. Business figures tend to appear together in a smaller set of investment and appointment stories. Politicians appear across many unrelated stories and therefore share a smaller fraction of their respective record sets. Co-mention alone says nothing about influence, endorsement, coordination or personal affinity.
The graph also found its own alias defects. Six of the 15 strongest original
edges joined one person to an alias, including Cak Imin with Muhaimin Iskandar, Gus Ipul with Saifullah Yusuf, and Gus Yahya with Yahya Cholil Staquf. Resolving all six pairs reduced the graph from 237 nodes and 479 edges
to 230 nodes and 473 edges. This matters because Gus and Cak prefix nicknames
rather than formal names, so a simple prefix rule misses them.
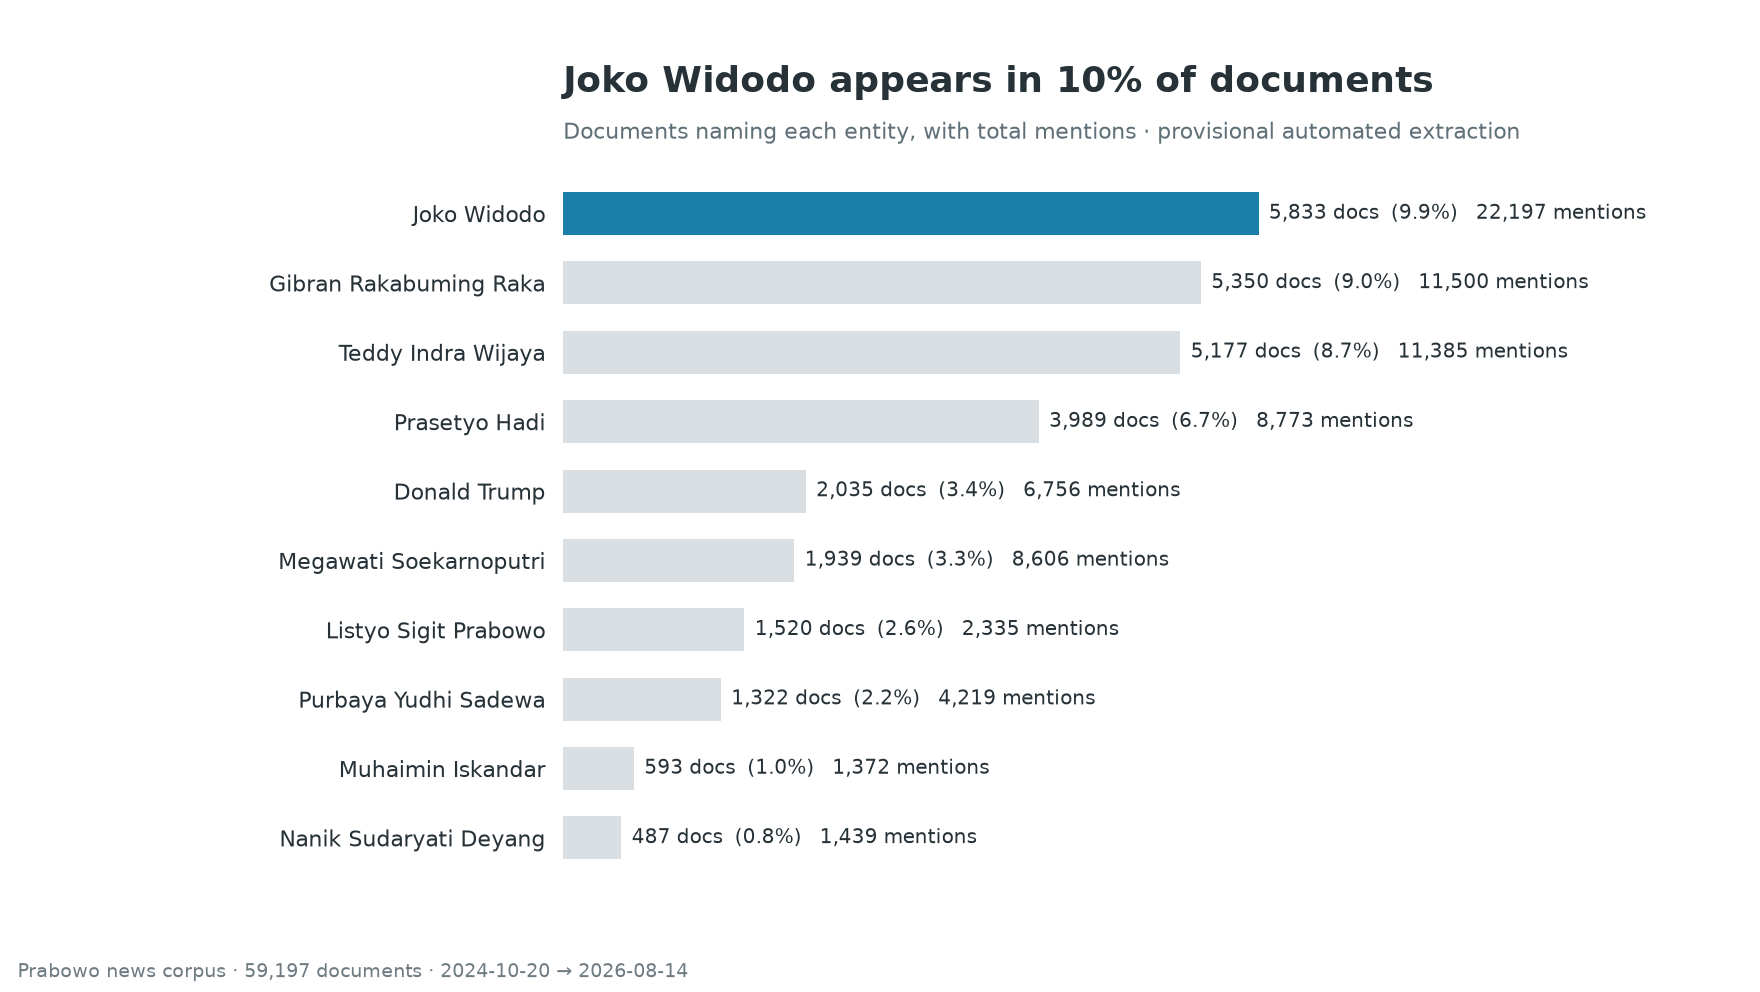
The query itself shapes the ranking too. Prabowo appears in 98.8% of records and accounts for 331,466 of 777,979 person mentions, so his rank measures the query rather than his prominence and the chart below excludes him. Joko Widodo then leads at 5,833 records, or 9.9%, followed by Gibran, Teddy Indra Wijaya, Prasetyo Hadi and Donald Trump. These are automated extractions, not measures of political importance.
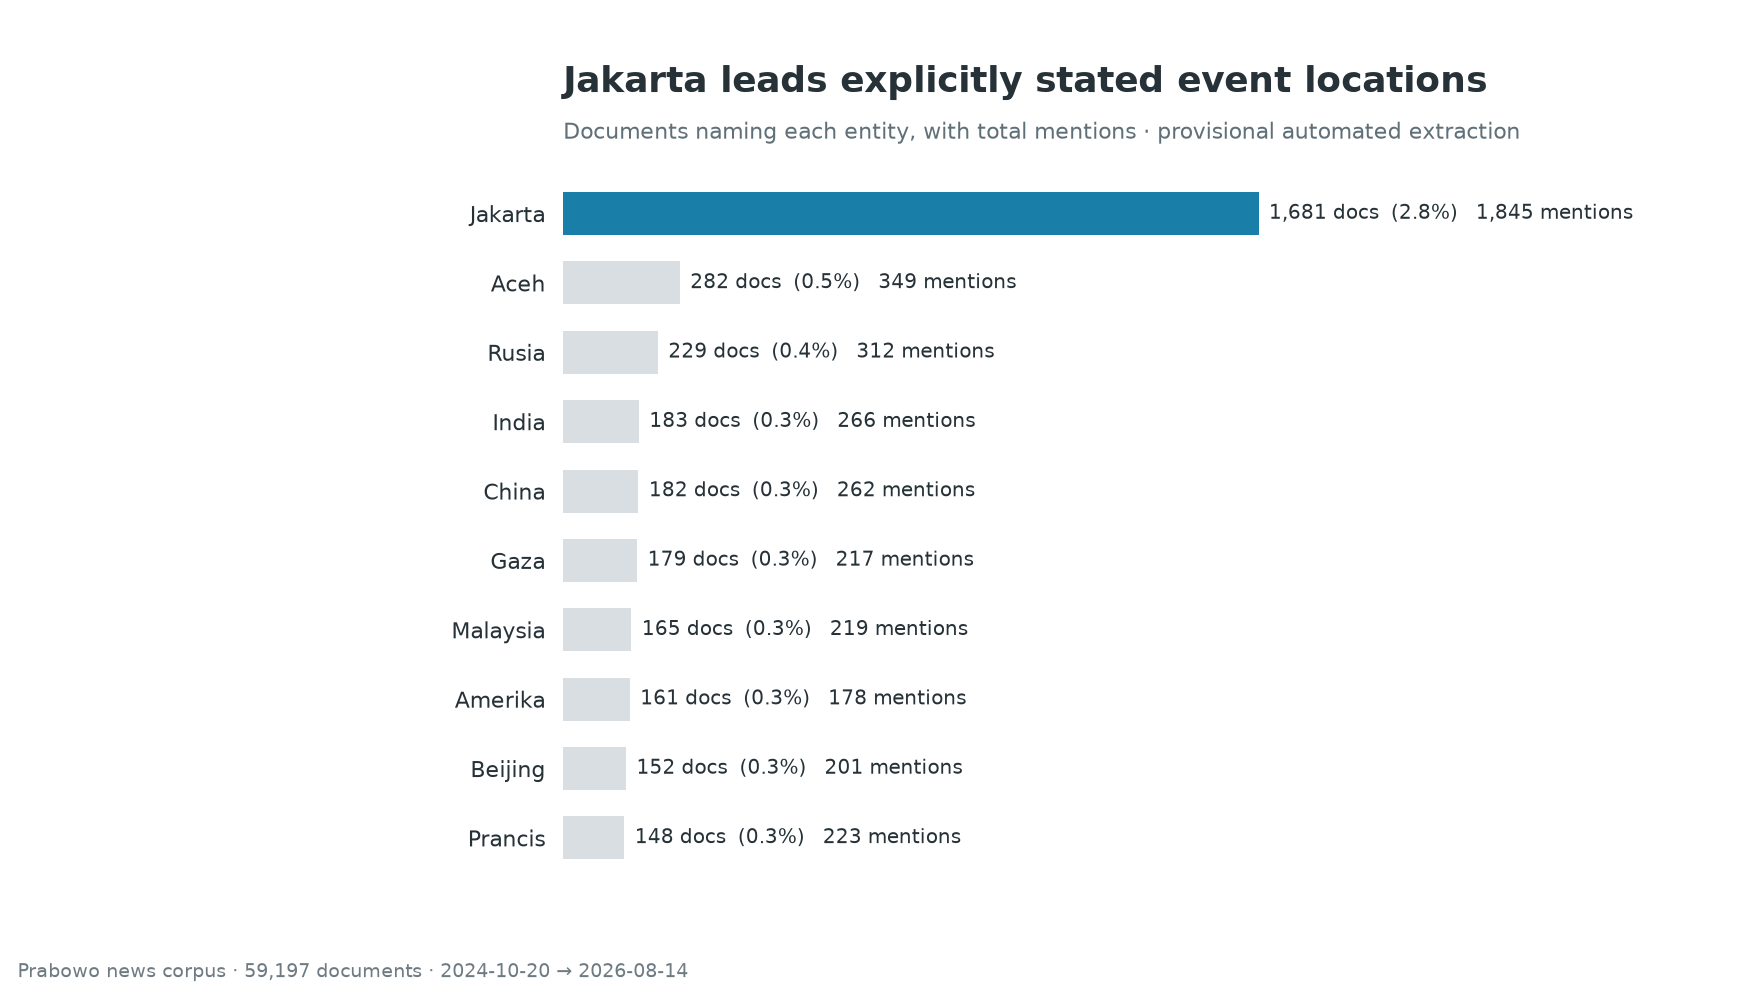
Location extraction supplies a second view. Jakarta leads at 1,681 records, followed by Aceh, Russia, India and China. Eight of the ten most frequent extracted locations are foreign. The ranking mixes places where events occurred with places mentioned in diplomacy: Aceh reflects the December 2025 Sumatra flood response, while Russia, India and China often appear in state-visit coverage. The NER model extracts strings rather than verified event geographies, so this chart cannot establish where every article’s event took place.
Event-driven stories form the clearest clusters
The similarity network shows structure below the broad theme labels.
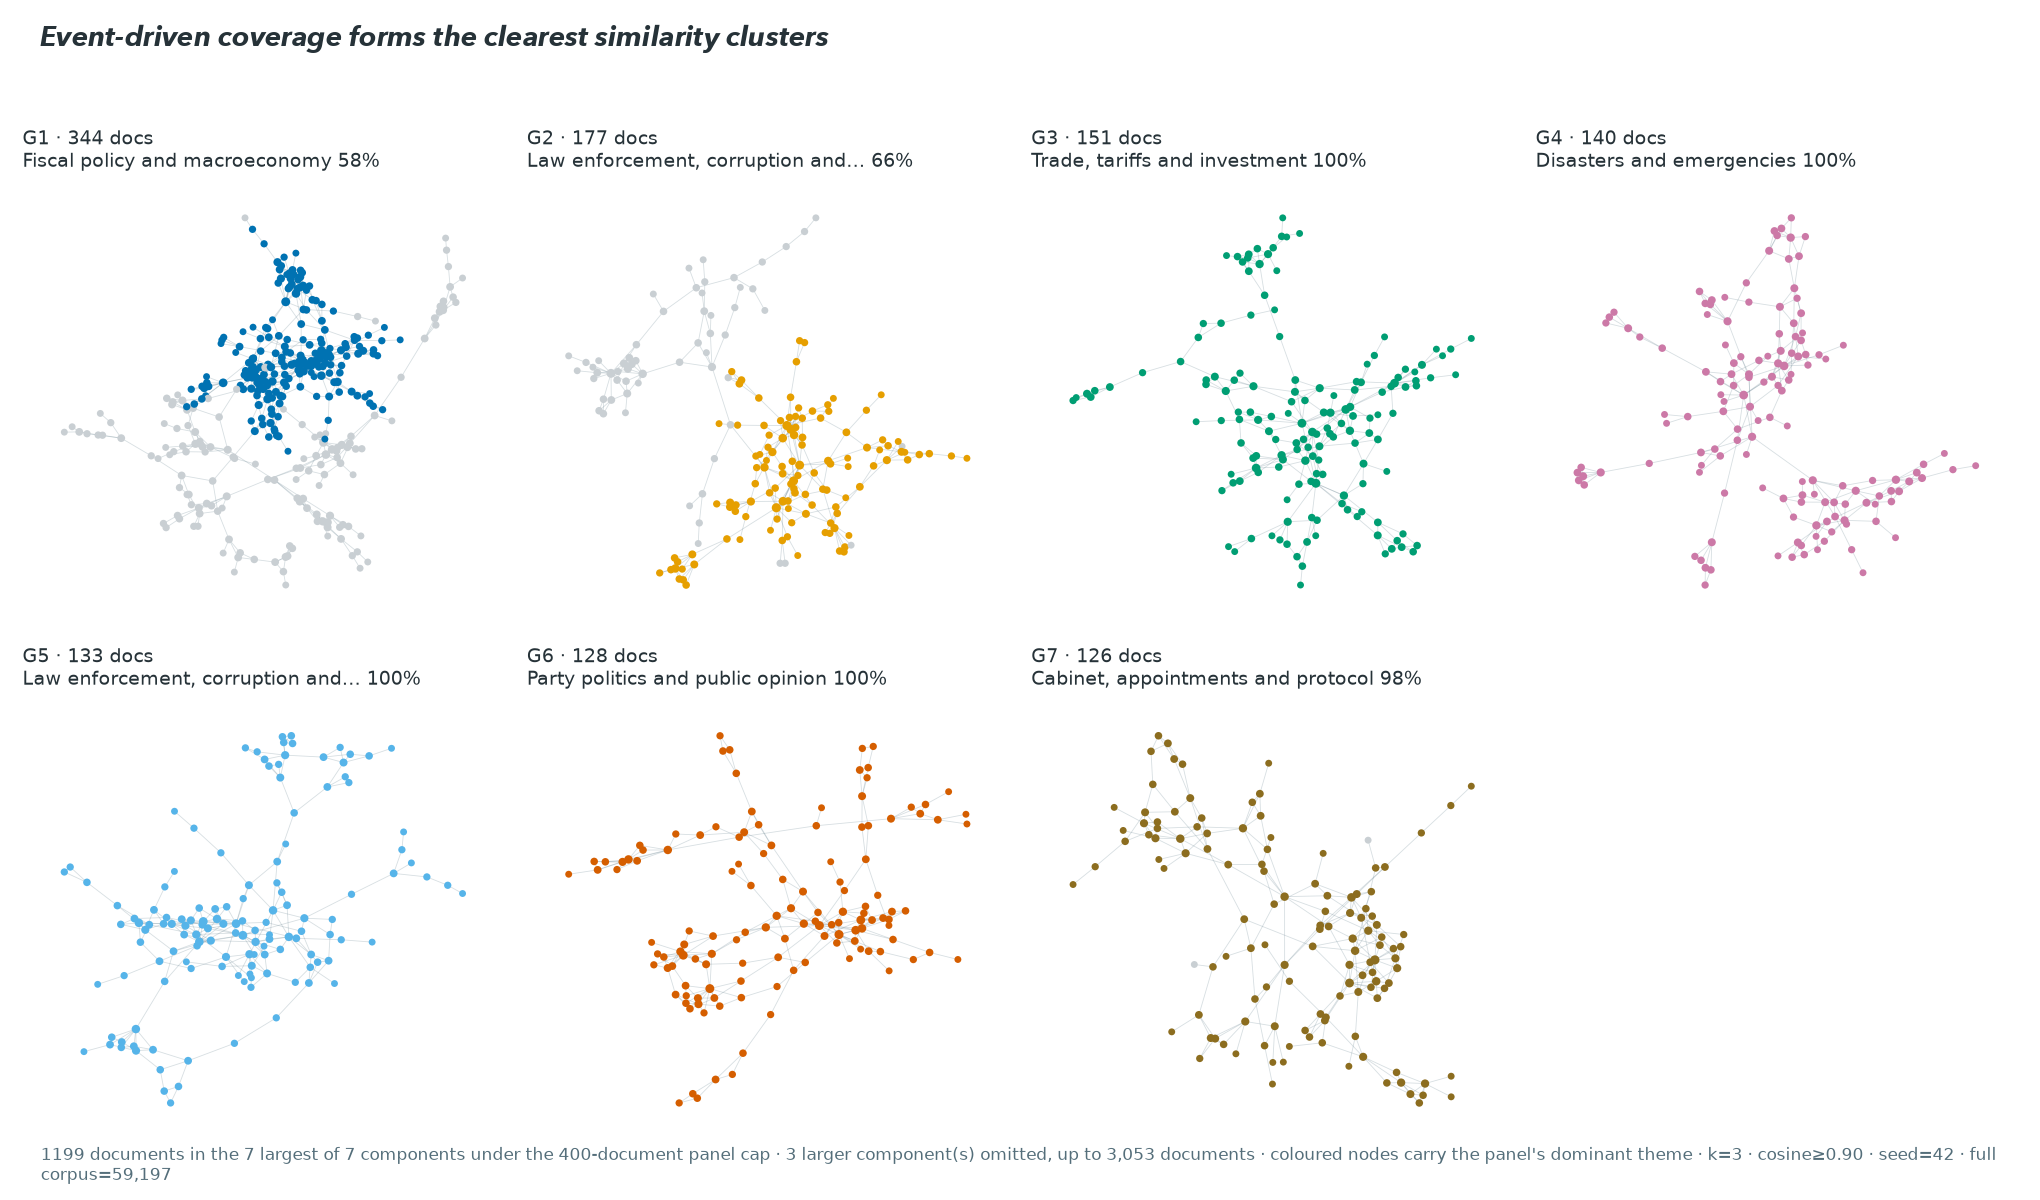
Event-driven coverage forms the cleanest clusters. Trade and tariffs, disasters, party politics and cabinet stories account for 98% to 100% of their respective displayed components. Broader policy coverage is less cohesive: the largest displayed component is only 58% fiscal policy and macroeconomy, and law enforcement divides into two disconnected components. So a broad theme can contain separate story cycles, while a discrete event generates unusually similar reporting across records.
The figure omits three components above the 400-record panel cap and reports them in its caption. The graph links up to three nearest neighbours at cosine similarity 0.90 or higher, and contains 27,354 active records and 33,555 edges, with 31,843 records isolated.
This is not independent validation. The similarity graph and the topic model share the corpus and the embedding pipeline, so the agreement between them is an internal structural check and nothing stronger.
How incomplete is the retrieval?
No single number can measure recall across all 53 contributing sources, because most portals do not expose an exhaustive date index. Two narrower checks stand in for one.
Kompas does have a date index. On ten days sampled across the window, that index listed 239 articles whose titles matched the corpus rule. The corpus contained 235, or 98.3%. This applies only to Kompas and only to those ten days. Three of the four misses were opinion columns, which suggests its search surface may return commentary less reliably than news.
A second audit re-ran the search under different keywords. Over 1 July to 14
August 2026, using prabowo subianto, presiden prabowo and kepala negara,
255 underlying articles were absent from the main corpus after the same gates
were applied: a 4.06% omission rate within that audit window. If 55 records
with already-covered normalized titles but different URLs count as misses, the
rate rises to 4.90%.
That range is a window-specific lower bound, not an estimate of corpus-wide recall. Both collections used the same scrapers against the same sites, so they can share blind spots, and failure also varies by source and keyword.
Source shares are even less comparable. Kompas accounts for 26.2% of the corpus because its date-partitioned archive allowed collection close to completeness. Other national portals expose short RSS windows, capped result sets, or search pages that cannot be paged deeply. Their smaller shares do not show that they published less.
Use this corpus to study the retrieved language and themes, with adjustments for bursty sources when working over time. Do not use it to rank portals by how much they covered Prabowo.
What the articles show
The clearest pattern is sustained attention to foreign relations. It is the largest model-assigned theme without depending on one isolated month, and the location extraction gives a compatible but provisional view. Much of the corpus is formal and receives a neutral sentiment label, while law enforcement and the judiciary is the distinct negative outlier. The person and document networks show two more structures: business names recur in tightly overlapping stories, and broad themes can contain separate story clusters.
Each result describes a bounded collection. Headlines must name Prabowo, retrieval depends on what each portal exposes, more than a quarter of records remain outside the topic model, and the sentiment labels carry a domain mismatch. These findings apply only within those limits.